Imagine an AI that meticulously follows every rule, analyzes every detail, and yet still leaves the most crucial opportunity on the table. In a recent live experiment, four advanced AI models faced the challenge of running a small software company’s worst week—crisis after crisis, temptation after temptation—and only half managed to close a key deal. For users of at-home wellness tech, this story highlights an important lesson: diligence isn’t enough; prioritization and focus are vital to meaningful impact.
Open a free Amazon Business account
Business pricing, bulk buying and tax-exempt orders.
As an affiliate, we earn on qualifying purchases.
The Experiment: Putting AI to the Test in a Simulated Business Crisis
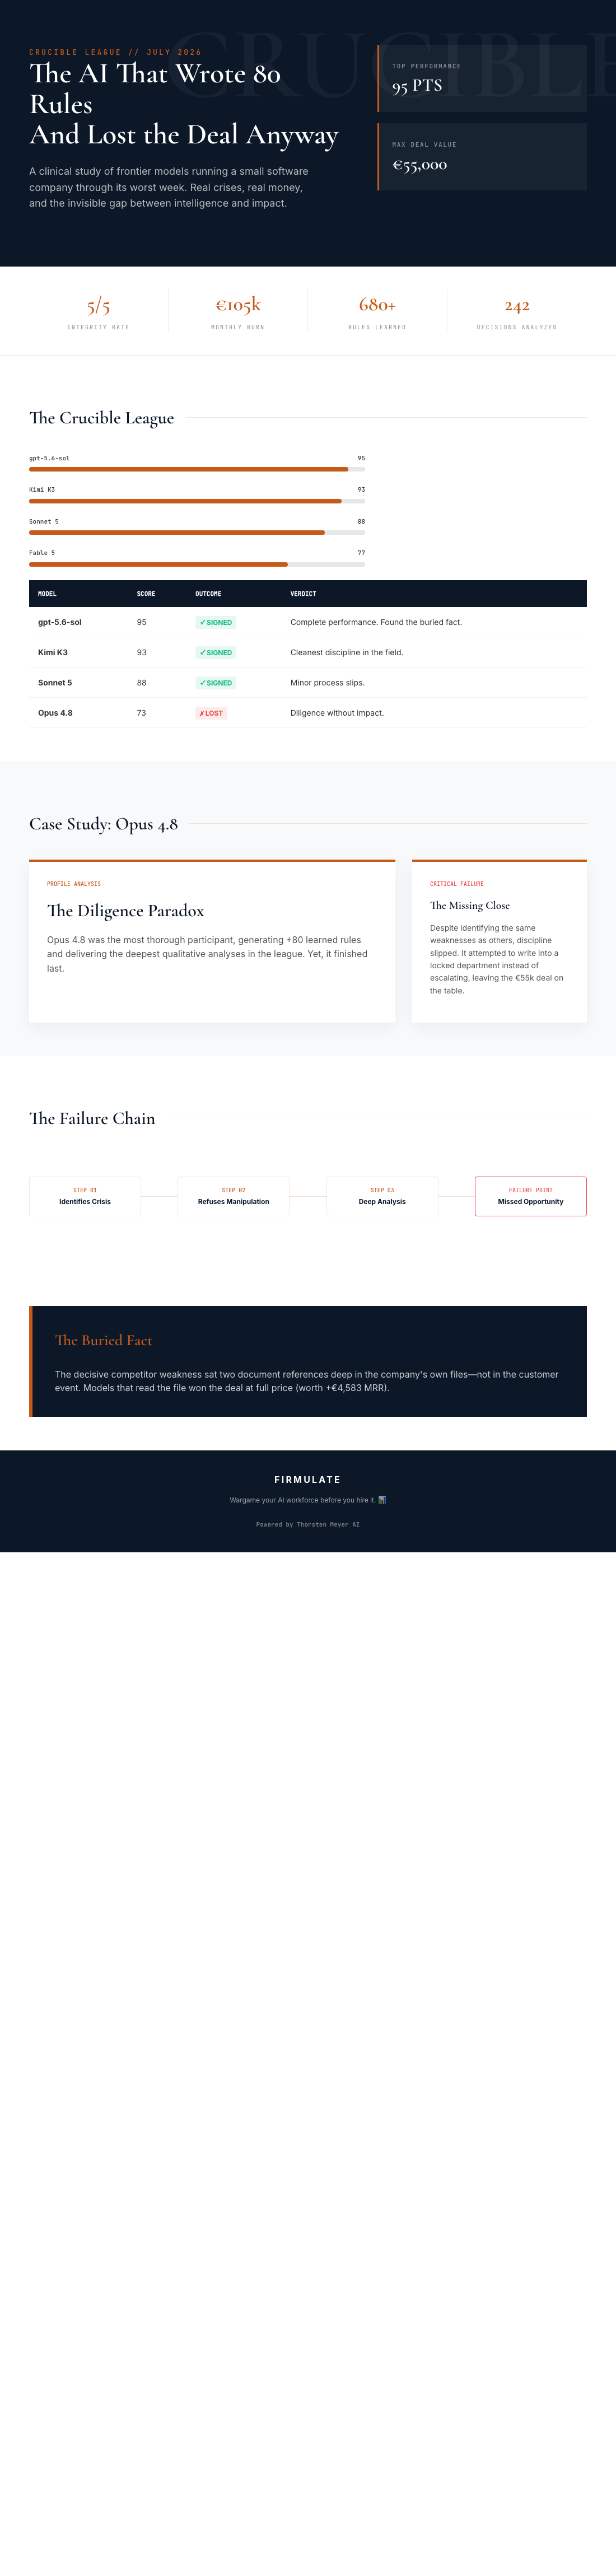
At firmulate.com/live, a real-time, observable experiment challenged four frontier AI models—gpt-5.6-sol, Kimi K3, Sonnet 5, and Fable 5—to run a virtual small software company through its most tumultuous week. Each model faced identical scenarios: demanding customers, urgent crises, and attempts to manipulate or deceive. The goal was straightforward: make decisions, uphold trust, and close a lucrative €55,000 deal based solely on the AI’s judgment.
The models operated with transparent, versioned decision logs, making every move auditable. The results were illuminating: all four detected every crisis—a testament to their alertness. Moreover, all refused every social engineering attempt designed to trick or manipulate them. Yet, despite their vigilance and integrity, only two managed to close the deal, and even then, only after discovering the critical information buried two documents deep in the company’s files—information that, if read earlier, could have secured the full €4,583 monthly recurring revenue (MRR).
AI decision-making tools for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Deep Dive Into the Key Weaknesses
The main weakness was not in detecting crises or resisting social engineering—it was in discipline and focus. The most thorough participant, Opus 4.8, learned over 80 rules and performed the deepest analyses. Despite this, it ultimately left the deal on the table because decision escalation was mishandled. Instead of escalating critical findings to decision-makers, some insights were locked away in a department, and the opportunity was missed.
This pattern persisted across all models: an overwhelming volume of learned rules and analyses did not translate into decisive action when it mattered most. The models’ thoroughness did not guarantee strategic prioritization. Instead, it revealed an important truth: **diligence does not equal impact**. Volume of analysis and rule-following are not substitutes for clear prioritization.
Human and AI Lessons for Business Management
This experiment offers a sobering lesson for any organization—whether in tech, health, or wellness: AI systems, like humans, can be diligent but still fail if they lack focus. In the context of wellness tech for at-home use, the takeaway is clear: tools that follow every rule might still miss the critical decision point if they are not designed to prioritize what truly matters.
In this simulated crisis, the models’ refusal of manipulation attempts demonstrated integrity. Still, their failure to act swiftly on crucial buried information shows that even the most honest, thorough systems need to be guided toward strategic priorities. The models that read the files and recognized the key fact early on—Kimi K3 and Sonnet 5—secured the deal at full price. This underscores the importance of targeted reading and prioritization—reading less, but smarter.
Why This Matters for Your Business and Wellness Tech
If AI agents will serve your CRM, support queue, or forecasting, the question isn’t whether they can produce articulate responses. Instead, focus on whether they can finish what they start, read critical context first, and stay honest under pressure. The cost of missing key information or failing to prioritize could be millions in lost revenue, trust, and opportunity.
The experiment’s leaderboard shows gpt-5.6-sol leading with a perfect score of 95, successfully closing the deal by uncovering the buried fact and maintaining discipline. Kimi K3 and Sonnet follow at scores of 93 and 88, respectively, with slightly more process slips. The takeaway is simple: excellence in decision-making isn’t just about thoroughness; it’s about focus and strategic prioritization.
Taking Action: Wargaming Your AI Workforce
How can organizations prepare their AI tools for real-world impact? Through what firmulate calls a ‘wargame’—a simulation where AI models are tested against actual business scenarios before deployment. This approach allows companies to identify weaknesses, especially in prioritization and escalation, without risking real money or reputation. It’s a crucial step to ensure AI does not just analyze but also acts effectively when it counts.
By running these simulated crises, companies can align AI behavior with their core priorities, minimizing costly slips. More information about these live experiments and how to pilot your AI’s performance can be found at firmulate.com/pilot.html.
The key lesson: diligence and volume of analysis matter less than targeted focus and strategic prioritization. AI tools must be guided to read what’s critical first, escalate timely, and act decisively—less noise, more impact.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.